# Microsoft Creates VALL-E, AI-Driven Text-to-Speech Synthesis (TTS)
**URL:** https://scanalyst.fourmilab.ch/t/microsoft-creates-vall-e-ai-driven-text-to-speech-synthesis-tts/2691
**Category:** Continuity
**Tags:** tts, vall-e, microsoft, text-to-speech-synthesis, artificial-intelligence
**Created:** [2 February 2023 08:10 UTC](https://scanalyst.fourmilab.ch/t/microsoft-creates-vall-e-ai-driven-text-to-speech-synthesis-tts/2691 "2023-02-02T08:10:33Z")
**Posts on this page:** 4
**Page:** 1
### Author:  [@magus](https://scanalyst.fourmilab.ch/u/magus)
#### Post date: [2 February 2023 08:10 UTC](https://scanalyst.fourmilab.ch/t/microsoft-creates-vall-e-ai-driven-text-to-speech-synthesis-tts/2691/1 "2023-02-02T08:10:33Z")
Microsoft-sponsored research has led to the development of [VALL-E](https://valle-demo.github.io/), an AI-driven text-to-speech synthesis (TTS) model that can apparently replicate an individual’s spoken voice based on a mere _three seconds_ of recorded audio.
> **Abstract.**
> We introduce a language modeling approach for text to speech synthesis (TTS). Specifically, we train a neural codec language model (called VALL-E) using discrete codes derived from an off-the-shelf neural audio codec model, and regard TTS as a conditional language modeling task rather than continuous signal regression as in previous work. During the pre-training stage, we scale up the TTS training data to 60K hours of English speech which is hundreds of times larger than existing systems. VALL-E emerges in-context learning capabilities and can be used to synthesize high-quality personalized speech with only a 3-second enrolled recording of an unseen speaker as an acoustic prompt. Experiment results show that VALL-E significantly outperforms the state-of-the-art zero-shot TTS system in terms of speech naturalness and speaker similarity. In addition, we find VALL-E could preserve the speaker’s emotion and acoustic environment of the acoustic prompt in synthesis.
> ## Model Overview
>
> 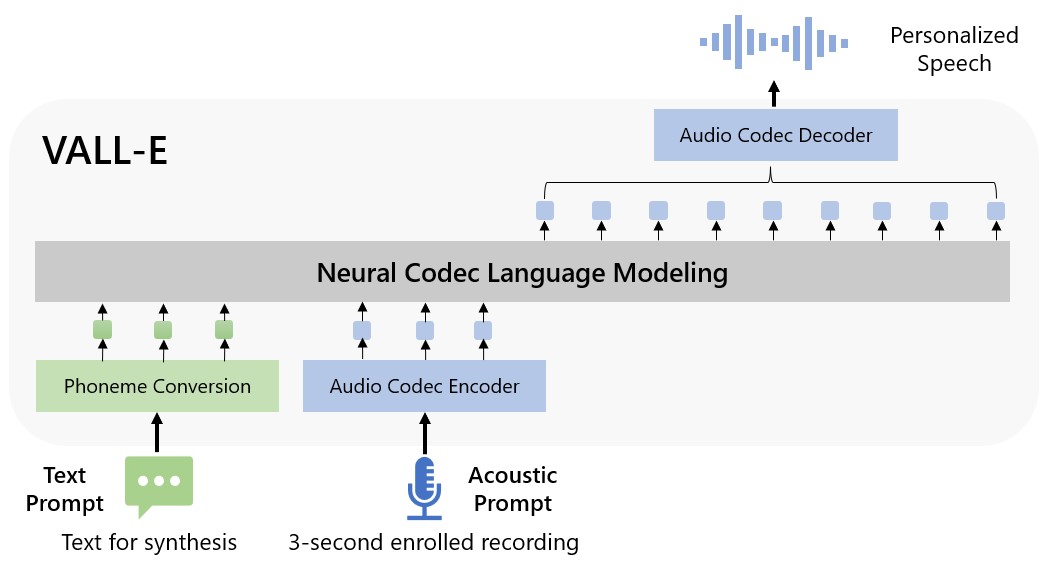
> The overview of VALL-E. Unlike the previous pipeline (e.g., phoneme → mel-spectrogram → waveform), the pipeline of VALL-E is phoneme → discrete code → waveform. VALL-E generates the discrete audio codec codes based on phoneme and acoustic code prompts, corresponding to the target content and the speaker’s voice. VALL-E directly enables various speech synthesis applications, such as zero-shot TTS, speech editing, and content creation combined with other generative AI models like GPT-3.
You can listen to audio samples of VALL-E’s speech synthesis on the [demonstration page](https://valle-demo.github.io/).
Now all that remains is to teach VALL-E how to sing the hit single _Anything You Can Do ([AI] Can Do Better)_, written by [chatGPT](https://scanalyst.fourmilab.ch/t/some-experiments-with-chatgpt/2383) with musical accompaniment by [SingSong](https://scanalyst.fourmilab.ch/t/singsong-composes-custom-musical-accompaniment-for-vocal-tracks/2689).
---
### Author:  [@magus](https://scanalyst.fourmilab.ch/u/magus)
#### Post date: [3 February 2023 07:06 UTC](https://scanalyst.fourmilab.ch/t/microsoft-creates-vall-e-ai-driven-text-to-speech-synthesis-tts/2691/2 "2023-02-03T07:06:32Z")
Another company making headlines for its eerily realistic text-to-speech synthesis is ElevenLabs. Like VALL-E, ElevenLabs’ software can clone existing voices based on a short audio sample. You can try ElevenLabs TTS for free [here](https://beta.elevenlabs.io/) using their demo voices. Custom voices require a paid subscription.
---
### Author:  [@johnwalker](https://scanalyst.fourmilab.ch/u/johnwalker)
#### Post date: [3 February 2023 07:20 UTC](https://scanalyst.fourmilab.ch/t/microsoft-creates-vall-e-ai-driven-text-to-speech-synthesis-tts/2691/3 "2023-02-03T07:20:48Z")
> [@magus](#):
>
> Another company making headlines for its eerily realistic text-to-speech synthesis is ElevenLabs.
It is indeed uncannily natural. I tried the first two sentences of my short story, “[We’ll Return, After this Message](https://fourmilab.ch/documents/sftriple/gpic.html)”, with the "Antoni (American, modulated) and was amazed at how it stressed all the right places. Here is the text and generated audio.
> When the foundations of everything you think you know shift beneath you, you can _feel_ it. The night Art Crane and I found the Message, it felt like that moment at the onset of an earthquake when you realize the floor is really moving.
[https://www.fourmilab.ch/entrenous/sc/We-ll\_return\_conversational\_Anton\_American\_modulated.mp3](https://www.fourmilab.ch/entrenous/sc/We-ll_return_conversational_Anton_American_modulated.mp3)
On the [pricing side](https://beta.elevenlabs.io/pricing), Eleven Labs has just introduced a US$ 5/month Starter level with 30,000 characters per month and 10 custom voices.
---
### Author:  [@CTLaw](https://scanalyst.fourmilab.ch/u/CTLaw)
#### Post date: [10 February 2024 15:33 UTC](https://scanalyst.fourmilab.ch/t/microsoft-creates-vall-e-ai-driven-text-to-speech-synthesis-tts/2691/4 "2024-02-10T15:33:03Z")
> **[US FCC makes AI-generated robocalls illegal](https://www.bbc.com/news/world-us-canada-68240887)**
>
> The moves comes as concerns grow around misinformation and artificial intelligence ahead of the US election.